Uptime and performance monitoring, meaningful alerts, service-level objectives and incident response, engineered so your site and apps stay available and someone acts the moment they do not.
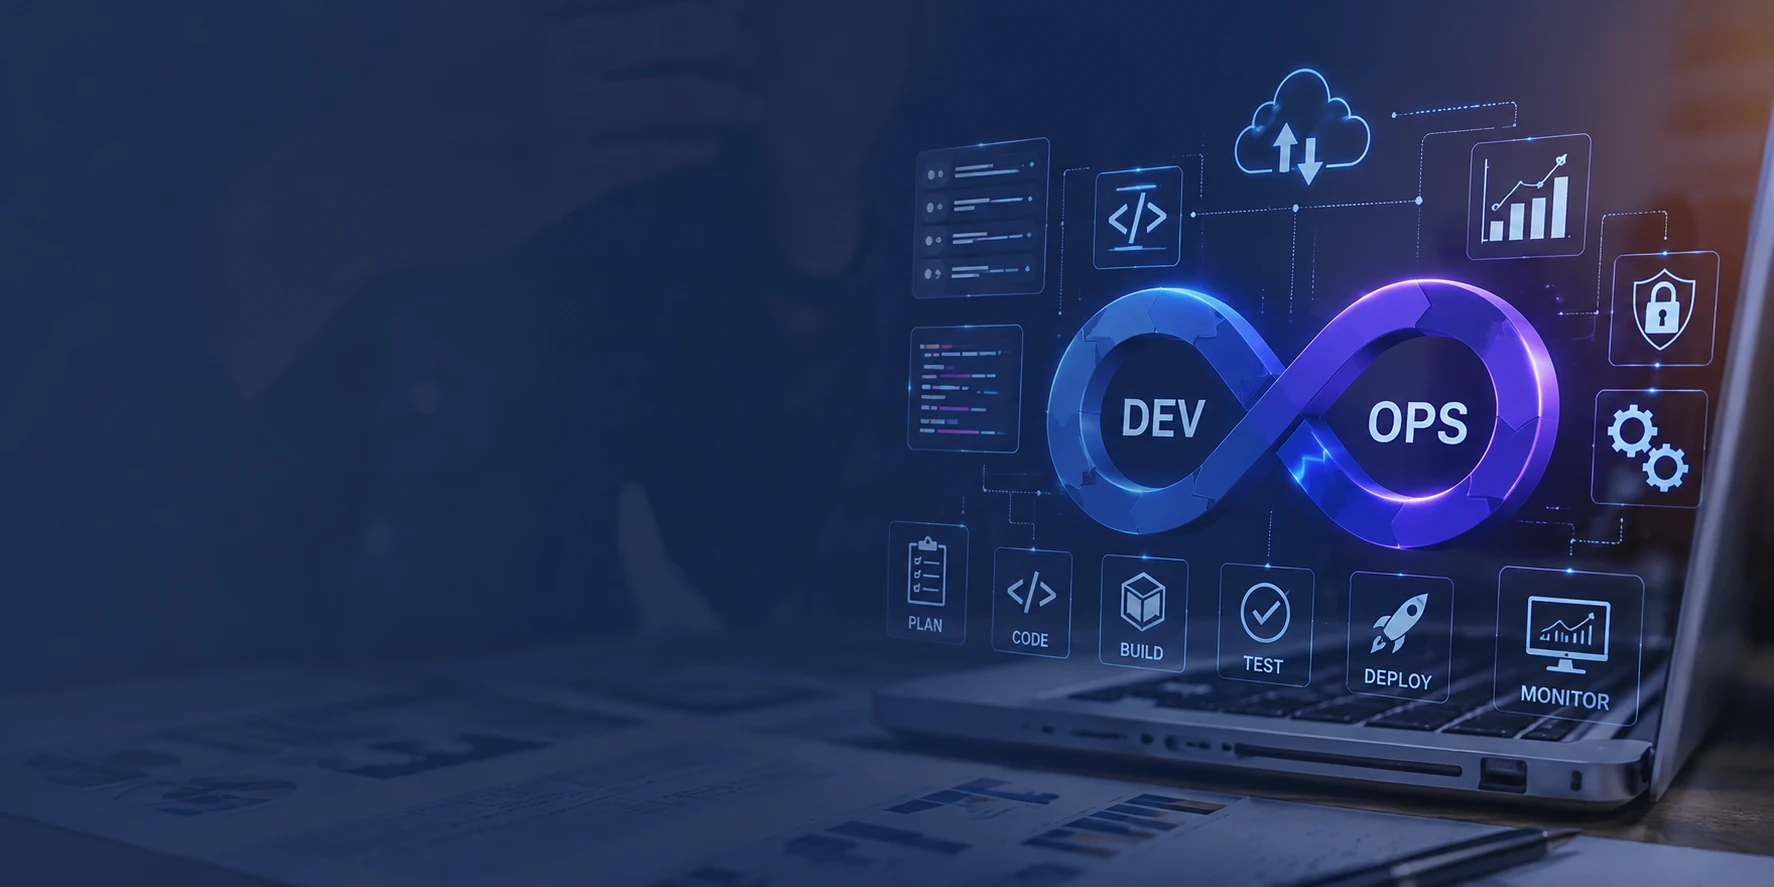
We build observability around what your customers experience, define how reliable the service must be and put the people and process in place to keep it there.
Multi-region HTTP, DNS, SSL and scripted transaction checks for login, search and checkout flows with status pages for your team.
Learn moreAPM with New Relic, Datadog or open-source stacks to trace slow requests, errors and database calls to the line of code.
Learn moreCentralised logging and infrastructure metrics with dashboards for CPU, memory, queues, disks and business KPIs.
Learn moreAlert rules tuned to reduce noise, escalation policies and on-call rotations with Indexiz engineers or your team.
Learn moreService-level objectives, error budgets, capacity planning and architecture fixes that remove recurring failure modes.
Learn moreRunbooks, incident command, customer communication templates and blameless reviews that turn incidents into fixes.
Learn moreScripted checkout checks across three storefronts with payment-gateway health alerts routed to on-call.
Defined availability and latency SLOs, tuned alerts from 400 to 30 a week and set up an escalation rotation.
Load-tested booking flows, fixed queue bottlenecks and set autoscaling policies ahead of the holiday peak.
Tools are easy to install; reliability comes from knowing what to watch, who responds and how problems get fixed for good. That is what we provide.
We monitor the journeys that make you money, not just whether a server pings.
Alerts are tuned so every page means something, which keeps on-call engineers sharp.
Alerts go to people who can fix the cause, with response times written into the plan.
Every incident ends in a review and a fix, so the same failure does not return.
We define what reliable means for your business as SLOs, instrument the system to show it and run the on-call process that keeps you inside the budget.
We work with commercial and open-source observability stacks on any cloud or hosting environment.
A proven process to turn your ideas into powerful digital solutions.
We identify critical user journeys, dependencies and failure risks.
We set up checks, APM, logs, dashboards and SLOs.
We tune alert rules and build escalation and on-call paths.
We respond to incidents, review them and remove root causes.
Answers to the questions we hear most often. Need more detail? Talk to our team.
Uptime monitoring tells you the site is down. Reliability engineering sets targets, finds why the site goes down and changes the architecture, process and alerting so it happens less. We offer both, and most clients start with monitoring and grow into SLOs.
Yes. Our engineers can take first-line on-call around the clock, escalate to your developers when needed, or we can design and run the rotation with your own team.
For most stores and apps a combination of synthetic checks, an APM such as New Relic or Datadog and error tracking with Sentry covers what matters. We also build Grafana and Prometheus stacks for teams who prefer open source.
No. We tune thresholds, group related alerts and use SLO burn rates so only actionable issues page someone. Reducing noise is a core part of the engagement.
Yes. Monitoring works with any host, cloud or platform. We integrate with your current provider and can also take over hosting under a managed plan if you prefer.
Tell us what you run and we will propose monitoring, alerting and on-call coverage that fits your risk and budget.
Or schedule a free consultation
AI · Software · Digital Commerce
info@indexiz.com
+92 344 615 6660
Get the latest insights and updates.
© 2026 Indexiz. All rights reserved.
WhatsApp us